One Origin, a Hundred Echoes: Teaching AI to Count Its Sources

Here is a trick question. An AI system finds one hundred articles that all agree on a claim. How many sources does it have?
If ninety-nine of those articles descend from a single press release, the honest answer is one. The claim carries one origin and ninety-nine echoes. Yet most retrieval systems, and most people, experience volume as confidence. Repetition manufactures the feeling of consensus, which is precisely why coordinated influence campaigns rely on it.
A proof-carrying architecture treats source independence as a first-class measurement. Before evidence counts toward confidence, the system asks where it came from.
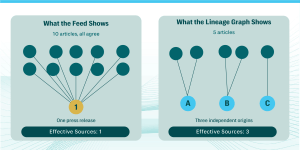
Figure 1. Ten articles descending from one press release count as one effective source; five articles from three independent origins count as three.
Lineage Before Confidence
Every piece of evidence carries lineage features: its canonical origin, its citation chain, syndication relationships, shared ownership, common data providers, near-duplicate clusters, and publication timing. The system groups sources that share an origin into a single evidence family, then counts corroboration in families, and the effective number of sources can come out far smaller than the raw count.
The confidence math follows. In place of a simple weighted average, the system computes a correlation-aware posterior. A dependence penalty reduces the marginal weight of evidence that is likely copied, syndicated, or drawn from the same upstream feed.
Research on Bayesian source dependence shows why this matters: majority voting can fail badly when the voters copy one another.
Independence is one interaction among several the math must respect. A normally reliable source may be stale for a claim about a current role. A primary document may be authoritative for its own statement while a stronger causal conclusion drawn from it needs separate support. Freshness itself decays at different rates: rapidly for a current office holder, almost not at all for a historical birth date. Simple weighted averages flatten all of these differences. A correlation-aware score models them, and it stays inspectable so a reviewer can see which factor moved the number.
Confidence That Means What It Says
The system then calibrates the output score against adjudicated outcomes, so that a displayed 90% is correct on about 90% of comparable claims. Calibration keeps the number honest, and sensitivity analysis keeps it explainable. The system can tell a reviewer, in plain terms, that confidence fell 18 points because the newly added sources turned out to be near-duplicates of the same origin.
Calibration is not an optional refinement. Research on modern neural networks consistently finds that raw model scores run overconfident and need an explicit calibration step against real, adjudicated outcomes. Without that step, a displayed 90% describes the model’s habits, and nothing more.
A claim supported by three genuinely independent evidence families is stronger than a claim supported by a hundred copies. Repetition hits diminishing returns quickly, and genuine independence is what earns additional confidence.
Rules That Confidence Cannot Override
Probability describes how well the evidence supports a claim. Acceptance runs through a separate proof engine, which applies hard rules that gate the answer regardless of how confident the score looks:
• The system may not present an expired policy as current.
• A quotation cannot support a stronger proposition than the quoted text entails.
• The system may not accept both a claim and its exact time-qualified negation.
• Measurements need compatible units before any comparison.
A hard-rule failure blocks the output or routes it to human review, no matter what the confidence score says.
Measuring Manipulation on Observable Dimensions
The same machinery generalizes to noise and propaganda. Manipulation rarely announces itself, so the system measures observable dimensions separately: factual support, provenance, amplification, framing, selection bias, coordination, authenticity, and residual uncertainty. A coordinated cluster can be factually correct, and a perfectly authentic document can carry a false claim. Keeping the dimensions separate keeps the assessment contestable, and it anchors trust to evidence properties a reviewer can inspect.
Measurement then drives a recorded policy response. The system can discount a claim, contextualize it, quarantine it, or escalate it, and it logs the reason for each action. Sources stay available with their assessment attached, because a low-reliability source can still be valuable as evidence of what a group is asserting, even when it proves nothing about the world.
For organizations operating in contested information environments, this machinery determines whether the AI amplifies the loudest narrative or checks who is doing the talking before it answers.
The final article in this series turns to the machinery underneath: why one model cannot do all of this, and how a hybrid fabric of models and deterministic services makes proof-carrying AI fast enough and affordable enough to run.

John "JT" Robinson
Chief Technology Officer
Get to the Core of More
Discover how Kentro helps organizations build AI systems that not only withstand scrutiny but can redefine the standards of trust and transparency.